

StatsPAI is for empirical researchers who would normally jump between Stata, R, and Python. Its goal is to make common Stata/R econometrics and causal-inference workflows feel native in Python: load a dataset, estimate a model, inspect diagnostics, export tables, and hand the result to an agent or notebook without leaving one API.
It is meant to be a practical replacement path for new Python-first work:
- Stata-style routines:
regress,ivregress,reghdfe,csdid,rdrobust,synth,psmatch2,esttab/outreg2. - R-style routines:
lm,fixest,did,rdrobust,Synth,DoubleML,MatchIt,modelsummary,broom. - Python-native outputs:
.summary(),.tidy(),.plot(),.to_latex(),.to_docx(),.to_agent_summary()where supported by the result object. - Agent-native access: every public function is registered with a
machine-readable schema (
sp.list_functions(),sp.describe_function(),sp.function_schema()), and the bundledstatspai-mcpserver exposes the estimators to MCP clients such as Claude Code, Claude Desktop, and Cursor. - Companion Stata tooling: our own
stata-codecan work with StatsPAI so agents can understand existing Stata workflows, translate them into Python, and cross-check results more smoothly. - Companion skill repos:
Auto-Empirical-Research-Skills,AER-Skills,Awesome-Journal-Skills, andPaper-WorkFlowcan work alongside StatsPAI and an agent as the methods, journal, manuscript, and reproducibility skill layer.
StatsPAI is not a promise that every Stata/R command is bit-for-bit identical.
The API is broad, and the numerical evidence behind it is uneven: some
estimators are checked against R/Stata on identical data, others only against
known-truth simulations, and many are API-stable without a numerical-parity
claim yet. Every function carries a validation_status that says which case
applies: validation_status distinguishes certified/validated evidence from API-stable breadth. See
Validation before relying
on a number for publication.
pip install statspaiPython 3.9 – 3.13. The core install covers estimation, diagnostics, the bundled
datasets, and .xlsx / .docx / LaTeX export. Plotting and heavier backends
are optional extras:
| Extra | Adds | Needed for |
|---|---|---|
statspai[plotting] |
matplotlib, seaborn, plotly | .plot(), sp.ggdid(), sp.interactive() and other figures |
statspai[fixest] |
pyfixest (Python ≥ 3.10) | sp.fixest.* wrappers and the pyfixest cross-validation engine |
statspai[bayes] |
PyMC, ArviZ | Bayesian estimators |
statspai[neural] / statspai[deepiv] |
PyTorch | neural causal models, DeepIV |
statspai[performance] |
JAX | accelerated backends |
statspai[spatial] |
geopandas, libpysal, shapely | shapefile / geometry-based spatial weights |
The interactive figure editor additionally needs ipywidgets inside Jupyter.
import statspai as sp

print(sp.datasets.list_datasets()[["name", "design", "source"]])
StatsPAI bundles 14 datasets that load offline. Most are real published
extracts (source == "bundled CSV"): Card (1995) NLSYM schooling data,
LaLonde/NSW with a PSID comparison group, the U.S. Senate RD data distributed
with R's rdrobust, California Proposition 99, the castle-doctrine panel, and
NHEFS, among others. A few are deterministic simulated replicas calibrated
to a published design (source == "simulated"), including the
Callaway–Sant'Anna mpdta panel used below; their numbers are not the numbers
from the original data.
At a glance: 1,183 registered functions across 87 submodules; 397k LOC (core) + 252k LOC (tests). Run python scripts/registry_stats.py to reproduce these numbers.
| What you used before | Stata / R examples | StatsPAI entry point |
|---|---|---|
| OLS / robust SE | reg y x, vce(robust) / lm() + sandwich |
sp.regress(..., robust="hc1") |
| IV / 2SLS | ivregress 2sls / AER::ivreg() |
sp.ivreg("y ~ (d ~ z) + x", data=df) |
| High-dimensional FE | reghdfe / fixest::feols() |
sp.feols("y ~ x | firm + year", data=df) |
| Staggered DiD | csdid / did::att_gt() |
sp.callaway_santanna() + sp.aggte() |
| Regression discontinuity | rdrobust / rdrobust::rdrobust() |
sp.rdrobust() |
| Synthetic control | synth / Synth::synth() |
sp.synth() |
| Matching / PSM | psmatch2 / MatchIt |
sp.psmatch2(), sp.match() |
| Double machine learning | ddml / DoubleML |
sp.dml() |
| Post-estimation | test, margins |
sp.test(), sp.margins() |
| Publication tables | esttab, outreg2 / modelsummary |
sp.regtable() |
| Translate a command | — | sp.from_stata("reghdfe y x, absorb(id year)"), sp.from_r("feols(...)") |
sp.esttab(), sp.outreg2(), and sp.modelsummary() still exist, but they are
deprecated thin wrappers over sp.regtable() and emit a DeprecationWarning.
StatsPAI aims to be one broad Stata/R-style workbench. Several focused Python packages do one part of that job, often with a longer track record; if you only need that part, they are good choices.
| Package | What it focuses on | How StatsPAI relates |
|---|---|---|
pyfixest |
fixest-style OLS / IV / GLM with high-dimensional fixed effects, event-study DiD, wild bootstrap, tables | StatsPAI has its own sp.feols (checked against R fixest) and uses pyfixest as an optional wrapper and cross-validation engine. |
linearmodels |
panel models, IV / GMM, system estimation | A core StatsPAI dependency for parts of the panel module, and an independent engine in sp.cross_validate. |
DoubleML |
double/debiased ML (PLR, PLIV, IRM, IIVM), with an R twin | sp.dml is checked against DoubleML on identical learners and folds. |
EconML |
heterogeneous treatment effects: DML, causal forests, DR learners, IV, policy learning | sp.metalearner is checked against EconML's S/T/X learners. |
DoWhy |
graph-based model → identify → estimate → refute workflow; graphical causal models | StatsPAI has DAG and causal-discovery tools, but is estimator-first rather than graph-first. |
CausalPy |
Bayesian-first quasi-experiments in PyMC (plus OLS via scikit-learn): DiD, synthetic control, RD, ITS, IV | StatsPAI centres frequentist econometric conventions (clustered / robust SEs, bias-corrected RD, CS-DiD aggregation) and cross-language parity evidence. |
causallib |
scikit-learn-style IPW, standardization, doubly robust estimation, and causal evaluation | StatsPAI covers these alongside regression, panel, DiD, RD, and synthetic-control workflows in one API. |
Use StatsPAI when you want one package, one function registry, and one agent interface across the everyday Stata/R empirical workflow.
The outputs below were produced with StatsPAI 1.28.0 on the bundled datasets.
Long summaries are abridged (... marks omitted lines); the numbers are pinned
by tests/test_readme_examples.py and tests/test_synth_placebo_pvalue.py, so
they cannot silently drift from the code again.
Question: how much higher is log wage for one more year of schooling in the Card (1995) NLSYM data?
import statspai as sp

card = sp.datasets.card_1995()
ols = sp.regress(
    "lwage ~ educ + exper + expersq + black + south + smsa",
    data=card,
    robust="hc1",
)
print(ols.summary())
Result:
Model: OLS
Method: Least Squares
Dependent Variable: lwage
...
           Coefficient  Std. Error  t-statistic  P>|t|  [0.025  0.975]
Intercept       4.7337      0.0702      67.4718 0.0000  4.5961  4.8712
educ            0.0740      0.0036      20.3208 0.0000  0.0669  0.0812
exper           0.0836      0.0067      12.4165 0.0000  0.0704  0.0968
expersq        -0.0022      0.0003      -7.0443 0.0000 -0.0029 -0.0016
black          -0.1896      0.0174     -10.8781 0.0000 -0.2238 -0.1555
south          -0.1249      0.0154      -8.1339 0.0000 -0.1550 -0.0948
smsa            0.1614      0.0152      10.6374 0.0000  0.1317  0.1912

Model Diagnostics:
--------------------
R-squared           : 0.2905
...
Read it like a Stata/R regression table: conditional on experience, race,
region, and SMSA, one more year of schooling is associated with about 0.074
higher log wage (roughly 7.4%). This is a correlation, not yet a causal return:
schooling is plausibly correlated with unobserved ability, which motivates the
IV in example 2. The HC1 standard errors follow Stata's vce(robust) /
sandwich::vcovHC(type = "HC1") convention.
Question: instrument schooling with growing up near a four-year college
(nearc4).
import statspai as sp

card = sp.datasets.card_1995()
iv = sp.ivreg(
    "lwage ~ (educ ~ nearc4) + exper + expersq + black + south + smsa",
    data=card,
)
print(iv.summary())
Result:
Model: IV-2SLS
Method: Two-Stage Least Squares
Dependent Variable: lwage
...
           Coefficient  Std. Error  t-statistic  P>|t|  [0.025  0.975]
...
educ            0.1323      0.0492       2.6870 0.0072  0.0358  0.2288

Model Diagnostics:
...
First-stage F (educ)        : 16.7176
...
Partial R² (educ)           : 0.0055
Hausman F-stat              : 1.5390
Hausman p-value             : 0.2149
The IV estimate (0.132) is larger than OLS but about 13 times less precise.
The instrument is not strong — nearc4 explains only 0.55% of the residual
variation in schooling (first-stage F ≈ 16.7) — and the Hausman test does not
reject exogeneity of educ (p = 0.21). Default standard errors are the
unadjusted ones with the small-sample correction used by AER::ivreg (Stata:
ivregress 2sls ..., small); pass robust="hc1" for heteroskedasticity-robust
errors.
With a first stage this modest, report a weak-instrument-robust interval too:
ar = sp.anderson_rubin_ci(
    y="lwage", endog="educ", instruments=["nearc4"],
    exog=["exper", "expersq", "black", "south", "smsa"], data=card,
)
print(ar.summary())
Anderson-Rubin (AR) — weak-IV-robust confidence set
------------------------------------------------------------
level : 95%
grid : 401 points on [-0.359, 0.624]
confidence set : [0.0389, 0.2601]
Question: what is the average effect of minimum-wage increases on teen
employment in the Callaway–Sant'Anna mpdta design?
import statspai as sp

mp = sp.datasets.mpdta()   # simulated replica of R did's mpdta
gt = sp.callaway_santanna(
    data=mp,
    y="lemp",
    t="year",
    i="countyreal",
    g="first_treat",
)
overall = sp.aggte(gt, type="simple", bstrap=False)
print(overall.summary())
Result:
==============================================================================
  Callaway and Sant'Anna (2021) — aggte[simple]
==============================================================================

  ATT:      -0.032977 ***
  Std. Error:  (0.007765)
  [95% CI]:    [-0.048195,  -0.017758]
  P-value:     0.0000
...
  Observations:    2,500
...
The aggregated ATT is about -0.033 log points and statistically precise. The
bundled mpdta is a calibrated simulated replica, so this is not the number R
reports on the original mpdta data. What is checked: the same CSV run
through R did::att_gt() + aggte() and Stata csdid returns the same ATT
and standard error (Track A parity module 04_csdid).
Question: is there a party incumbency advantage at the zero-margin cutoff in U.S. Senate elections?
import statspai as sp

senate = sp.datasets.lee_2008_senate()  # rdrobust's Senate data: x = margin, y = vote share
rd = sp.rdrobust(data=senate, y="y", x="x", c=0)
print(rd.summary())
Result:
==============================================================================
  Sharp RD Estimation
==============================================================================

  RD Effect:       7.506502 ***
  Std. Error:  (1.741258)
  [95% CI]:    [4.093699,  10.919306]
  P-value:     0.0000

------------------------------------------------------------------------------
  Inference
------------------------------------------------------------------------------
      method  estimate     se      z  pvalue  ci_lower  ci_upper
Conventional    7.4141 1.4587 5.0826  0.0000    4.5551   10.2732
      Robust    7.5065 1.7413 4.3110  0.0000    4.0937   10.9193

------------------------------------------------------------------------------
  Observations:    1,297
...
  Bandwidth H:    17.7544
  Bandwidth B:    28.0281
...
  N Effective Left:    360
  N Effective Right:    323
...
The data are the extract of Cattaneo, Frandsen & Titiunik (2015,
doi:10.1515/jci-2013-0010) that ships
with R's rdrobust (the loader keeps its historical name): x is the party's
vote-share margin in the election at time t and y its vote share (0–100) in
the election at t+2, following rdrobust's own illustration. Barely winning at
t raises the vote share at t+2 by about 7.4 percentage points (conventional),
7.5 with robust bias correction; the headline line reports the robust
bias-corrected estimate and CI. On this data
the default MSE-optimal bandwidths, estimates, and standard errors match R
rdrobust::rdrobust() and Stata rdrobust (Track A parity module 06_rd).
Observations are 1,297 because 93 rows have a missing outcome.
Question: how did California's Proposition 99 affect cigarette sales?
import statspai as sp

prop99 = sp.datasets.california_prop99()
sc = sp.synth(
    data=prop99,
    outcome="cigsale",
    unit="state",
    time="year",
    treated_unit="California",
    treatment_time=1989,
)
print(sc.summary())
Result:
==============================================================================
  Synthetic Control Method
==============================================================================

  ATT:      -19.760529 *
  Std. Error:  (11.233914)
  [95% CI]:    [-41.778595,  2.257538]
  P-value:     0.0769

------------------------------------------------------------------------------
  Detailed Estimates
------------------------------------------------------------------------------
         unit  weight
         Utah  0.3768
      Montana  0.2831
       Nevada  0.1881
  Connecticut  0.0690
New Hampshire  0.0439
     Colorado  0.0391
...
The estimate says California consumed about 20 fewer packs per capita per year
after the intervention. The p-value is the in-space placebo rank: California's
post/pre RMSPE ratio ranks 3rd of the 39 states, so p = 3/39 ≈ 0.077. This
default matches on pre-treatment outcomes only; pass covariates= (e.g.
["lnincome", "retprice", "age15to24", "beer"]) for an ADH-style predictor
specification. That path re-solves the nested V-W problem for every placebo
state and is much slower: pass n_jobs=-1 to fit the placebos in parallel
(bit-identical results), or placebo=False while iterating on the
specification.
Read this number with its caveat, which the full summary also prints:
classical SCM weights are often not uniquely identified on empirical data, and
different correct solvers can land on different donor weights. StatsPAI's
native solver is certified on uniquely identified designs and labelled
identification-dependent elsewhere. On this specification R Synth reaches an
ATT of about -19.59 rather than -19.76; pass backend="synth" (needs a
local R with the Synth package; outcome-lag specification only) when you need
R's exact numbers.
sp.regtable() is the single table builder behind every format. Build the table
once, then write it wherever your co-authors need it:
import statspai as sp

card = sp.datasets.card_1995()
m1 = sp.regress("lwage ~ educ", data=card, robust="hc1")
m2 = sp.regress("lwage ~ educ + exper + expersq", data=card, robust="hc1")
m3 = sp.regress("lwage ~ educ + exper + expersq + black + south + smsa",
                data=card, robust="hc1")
m4 = sp.ivreg("lwage ~ (educ ~ nearc4) + exper + expersq + black + south + smsa",
              data=card, robust="hc1")

tbl = sp.regtable(
    m1, m2, m3, m4,
    model_labels=["OLS (1)", "OLS (2)", "OLS (3)", "2SLS (4)"],
    coef_labels={"educ": "Years of schooling", "exper": "Experience",
                 "expersq": "Experience squared", "black": "Black",
                 "south": "South", "smsa": "SMSA"},
    drop=["Intercept"],
    title="Returns to Schooling (Card 1995)",
    notes=["HC1 robust SE. Column (4) instruments schooling with nearc4."],
)
print(tbl)                    # terminal
tbl.to_excel("table1.xlsx")   # Excel
tbl.to_word("table1.docx")    # Word
tbl.to_latex()                # LaTeX source; also .to_markdown(), .to_html()
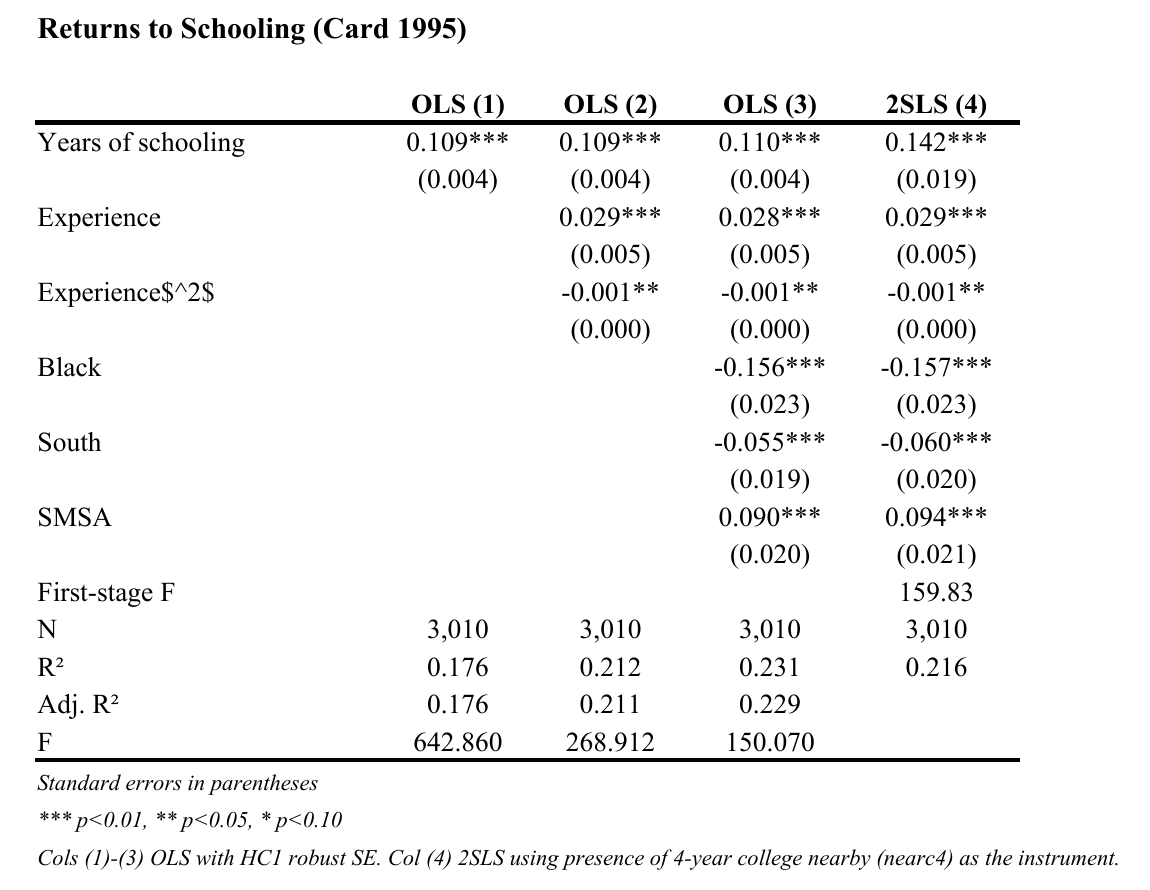
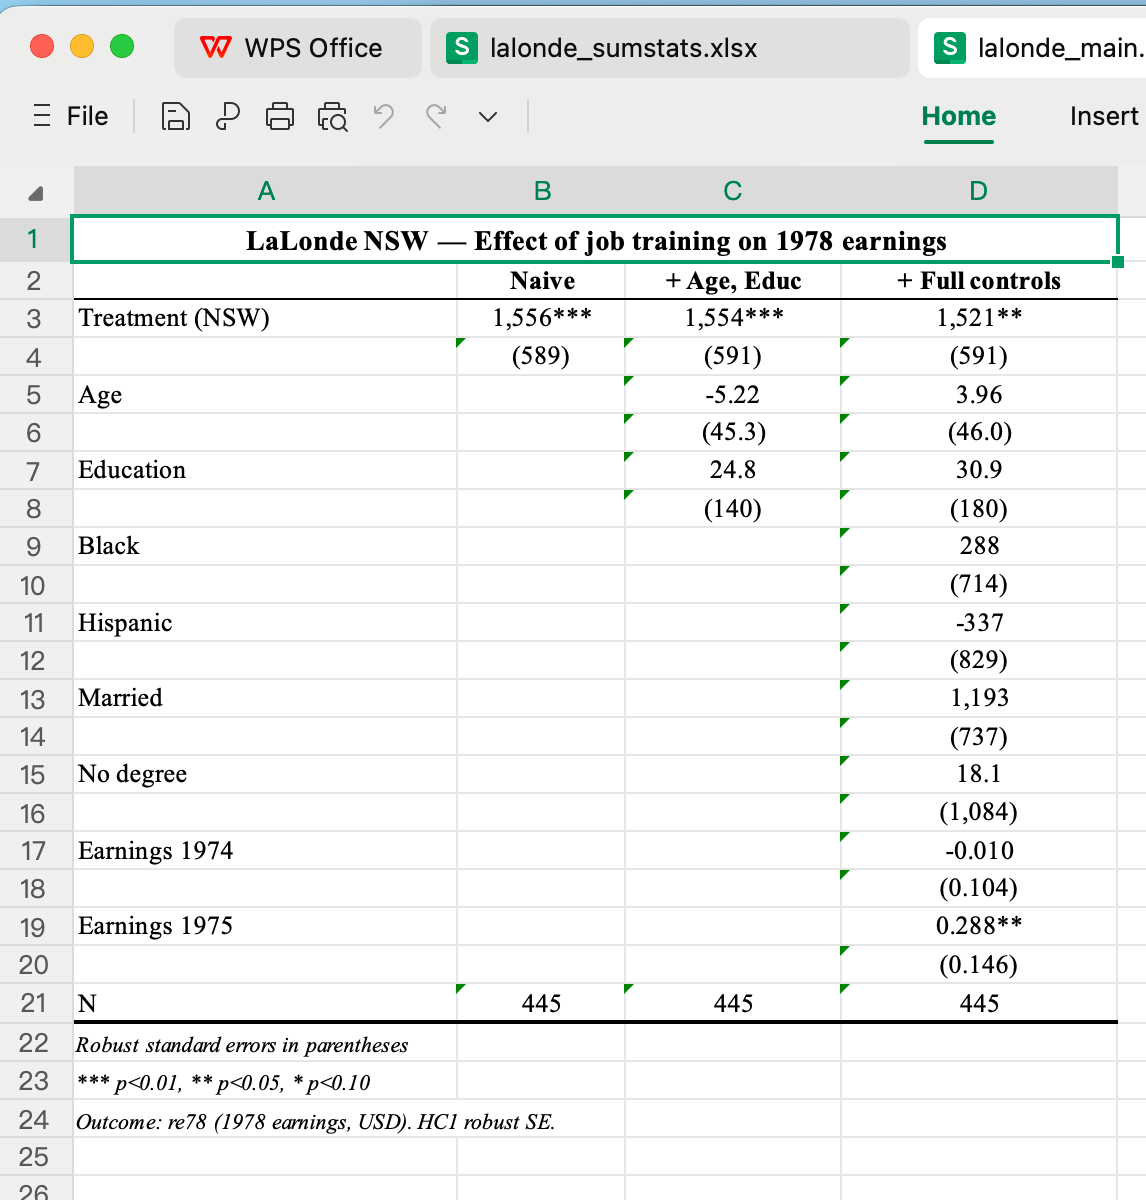
The images are the .xlsx files written by tbl.to_excel(), rendered with
LibreOffice: the Card (1995) table above, and a LaLonde/NSW table regressing
1978 earnings on NSW treatment with a PSID comparison group. The LaLonde table
is also a warning about observational comparisons: the treatment coefficient
moves from -635 to +1,548 once pre-treatment earnings and demographics are
controlled for. See the
export guide for journal
templates, standard-error formats, and single-model exports.
If you miss Stata's Graph Editor, use sp.interactive(fig) on any matplotlib
figure returned by StatsPAI. In Jupyter it opens an editing panel next to a
live preview, so beginners can adjust a figure without learning every
matplotlib option first. Requires pip install "statspai[plotting]" ipywidgets.
What it is for:
- change titles, labels, fonts, colors, markers, line widths, grids, legends, axis limits, figure size, and export DPI;
- switch among StatsPAI's publication themes (
academic,aea,minimal,cn_journal) and the built-in matplotlib and seaborn styles; - keep the data layer protected while editing cosmetic elements
(
protect_data=Trueby default); - export reproducible Python code for the edits, so the final figure can be regenerated from a script instead of being only a manual screenshot.
import statspai as sp

mp = sp.datasets.mpdta()
gt = sp.callaway_santanna(data=mp, y="lemp", t="year",
                          i="countyreal", g="first_treat")
agg = sp.aggte(gt, type="dynamic", bstrap=False)
fig, ax = sp.ggdid(agg)

editor = sp.interactive(fig)   # edit the plot in Jupyter
print(editor.generate_code())  # copy reproducible matplotlib edits
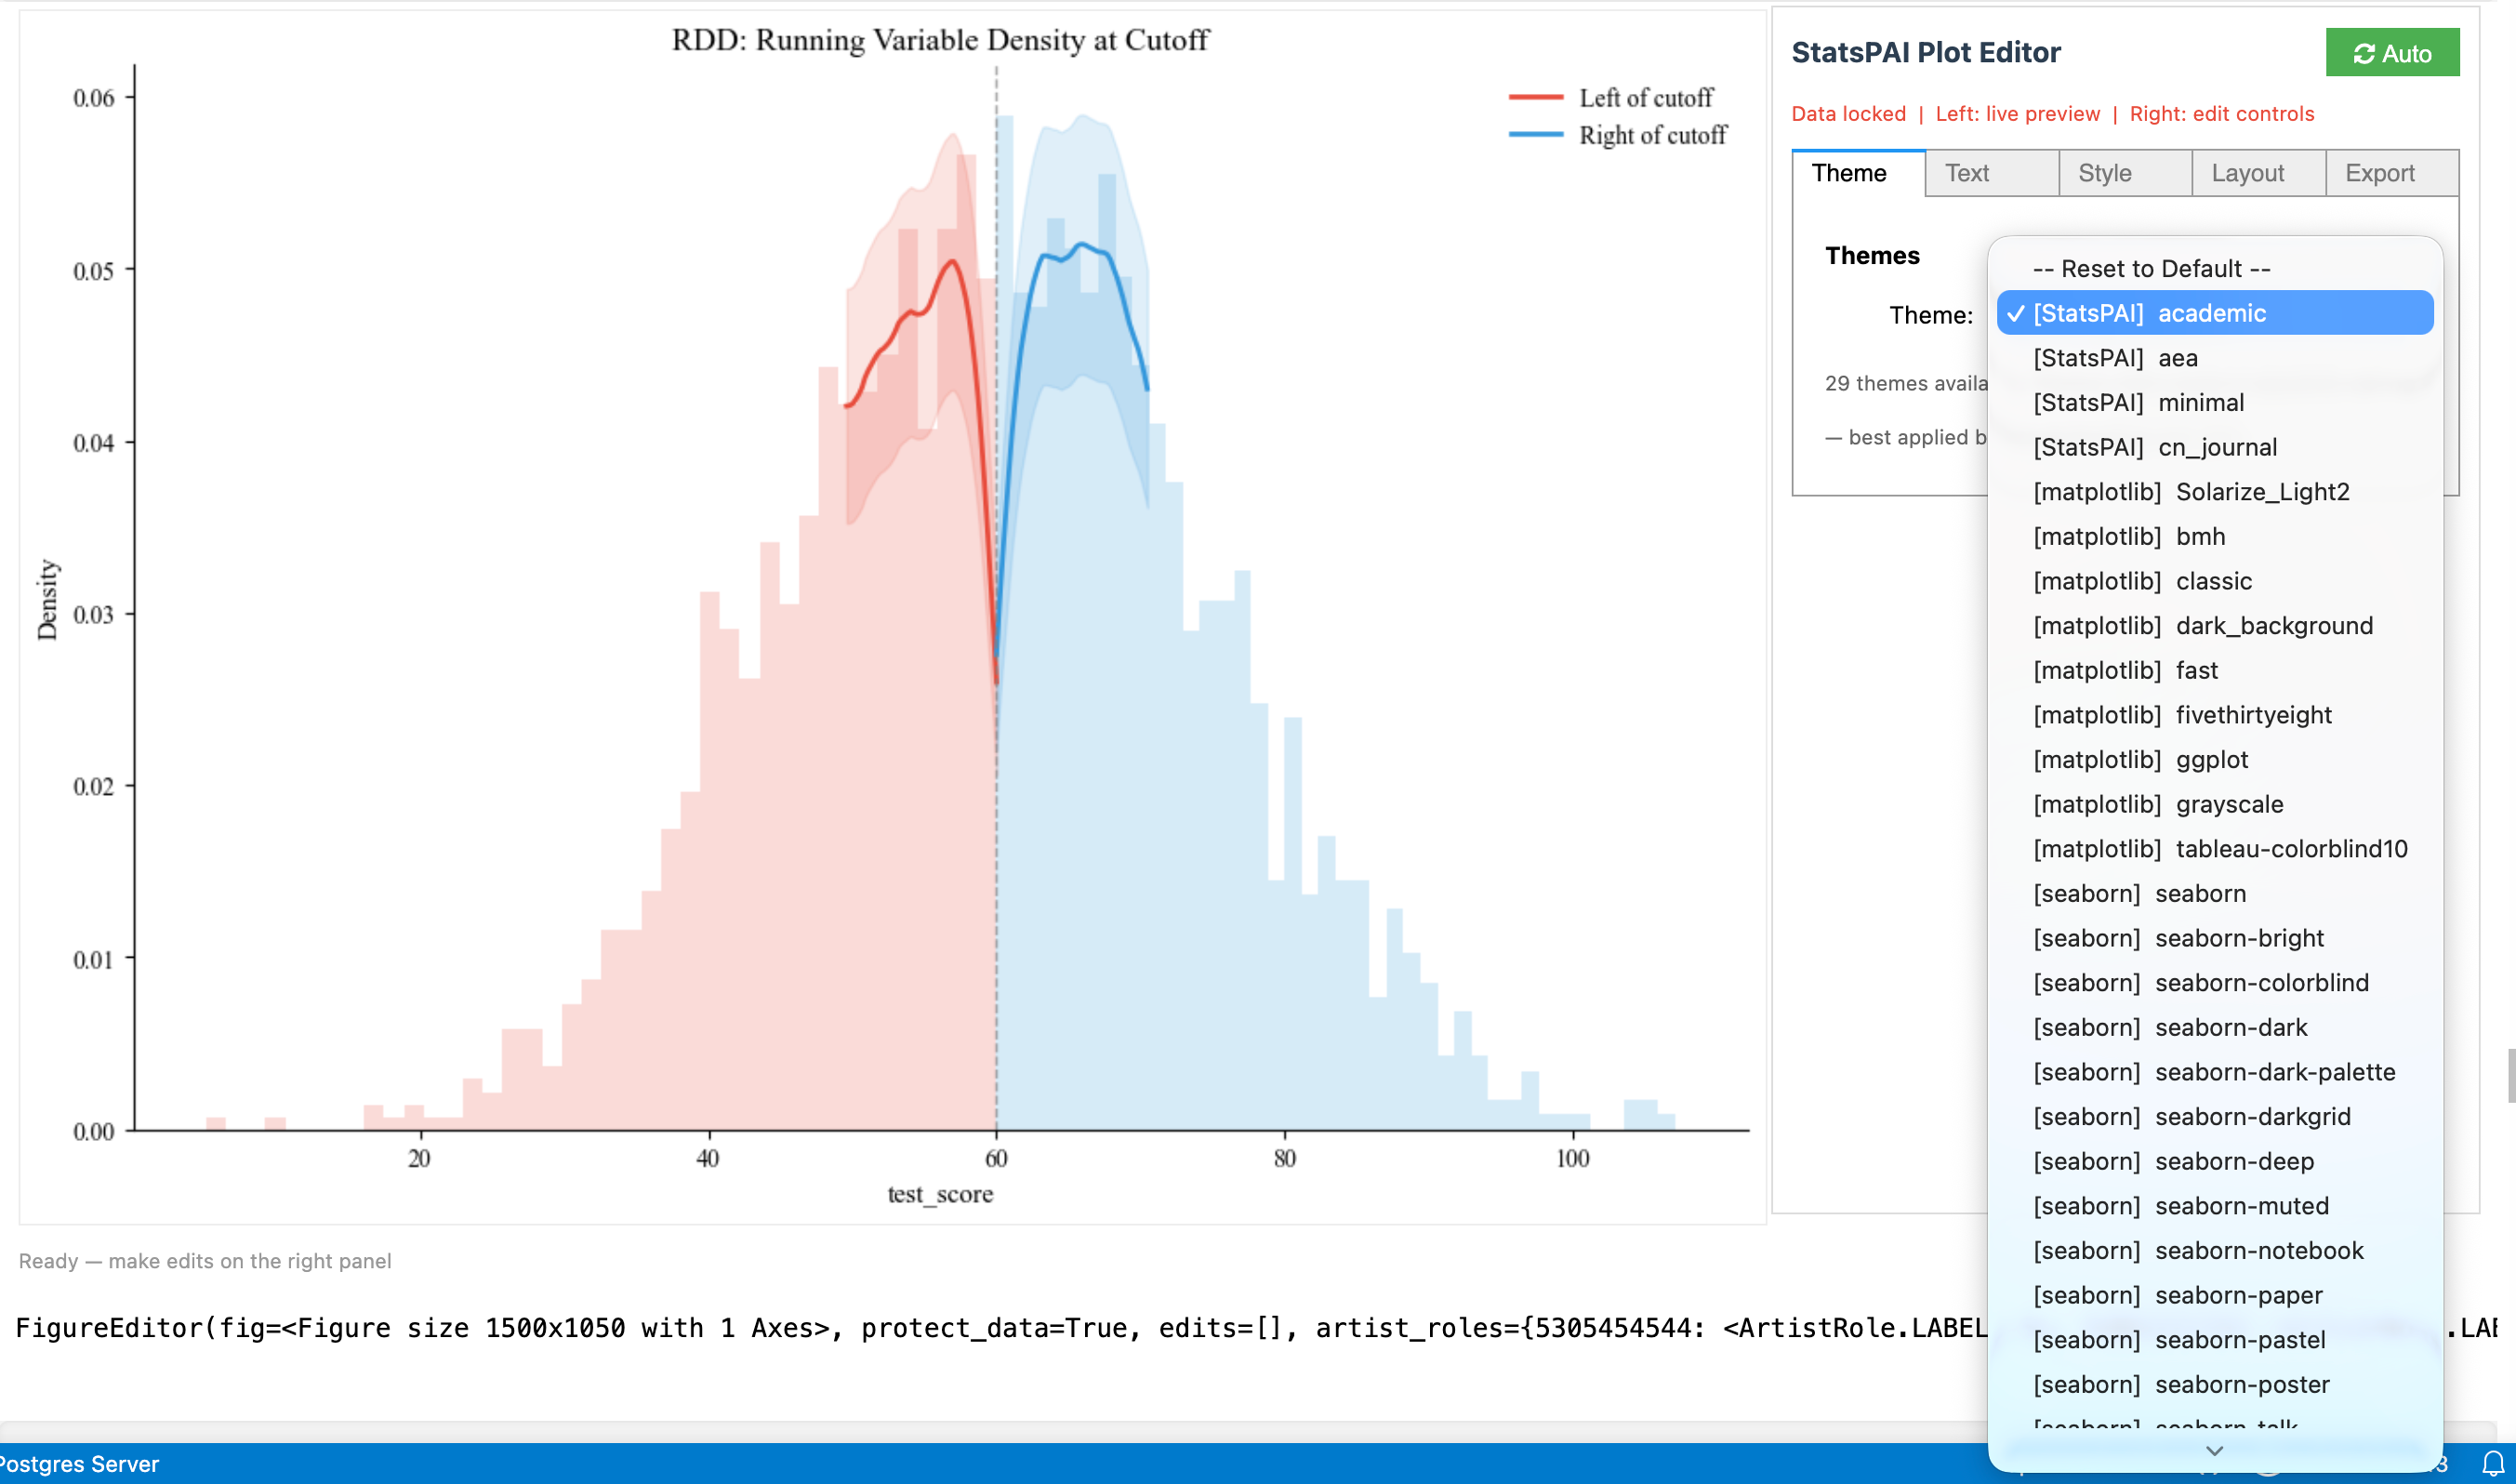
The screenshot above shows the intended workflow: preview on one side, editing controls on the other, and code export for reproducibility.
import statspai as sp

card = sp.datasets.card_1995()
r1 = sp.regress(
    "lwage ~ educ + exper + expersq + black + south + smsa",
    data=card,
    robust="hc1",
)
r2 = sp.ivreg("lwage ~ (educ ~ nearc4) + exper + expersq + black + south + smsa", data=card)

print(r1.summary())                          # human-readable table
print(r1.tidy().head())                      # broom-style dataframe
print(sp.test(r1, "black = south"))          # Wald test, like Stata's `test`
tbl = sp.regtable(r1, r2, model_labels=["OLS", "2SLS"])
tbl.to_word("table.docx")                    # Word table
tbl.to_excel("results.xlsx")                 # Excel table
Useful docs:
- Getting started and Cookbook
- Choosing an estimator: DiD, IV, RD, matching, synthetic control
- Migrating: from R, Stata/R command translators, shared argument grammar
- Exporting regression tables
- Agents: agent API, MCP workflow for economists
- Evidence: stability and validation tiers, parity matrix, tier census
The same registry that powers sp.help() is exposed three ways.
In Python — discover functions and their schemas without reading source:
import statspai as sp

sp.list_functions(category="causal")[:5]      # names
sp.describe_function("rdrobust")               # parameters, returns, validation
sp.function_schema("rdrobust")                 # JSON schema for tool calling
sp.from_stata("reghdfe y x, absorb(id year) vce(cluster id)")
# {'tool': 'feols', 'python_code': "sp.feols('y ~ x | id + year', data=df, cluster='id')", ...}
From the shell — statspai list, statspai describe rdrobust,
statspai search "synthetic control".
Over MCP — the package installs a statspai-mcp stdio server (pure Python,
no extra dependencies). It exposes several hundred estimators and diagnostics as
tools, plus workflow prompts (for example audit_did_result,
stata_command_workflow) and resources such as statspai://catalog. Tools take
a data_path (CSV, Stata .dta, and other formats pandas can read) and return
structured JSON with data provenance. For Claude Code:
claude mcp add statspai -- statspai-mcpFor Claude Desktop, Cursor, and other clients:
{
  "mcpServers": {
    "statspai": { "command": "statspai-mcp", "args": [] }
  }
}
See the MCP workflow guide for data handoff, result handles, and the recommended detect → estimate → audit loop.
StatsPAI has a large API surface, so validation status matters.
import statspai as sp

print(sp.describe_function("ivreg")["validation_status"])   # 'certified'
print(sp.list_functions(validation_status="certified")[:5])
Every registered function carries one of these tiers (counts as of 1.28.0):
validation_status |
Meaning | Functions |
|---|---|---|
certified |
compared with a named external reference implementation (R, Stata, or the method authors' Python package) on identical inputs, within a pre-registered tolerance | 223 |
validated |
known-truth simulation, published-number, coverage, or documented-convention evidence, but not in the main R/Stata harness | 206 |
api_stable |
stable public interface; unit tests exist, but no numerical-validation claim | 750 |
experimental |
method or API may still change | 3 |
In other words, roughly a third of the registered surface carries numerical evidence today. Breadth is not the same as validation; check the tier of the functions you depend on.
The tiers above are derived from an auditable parity index: every verified
function records what it was aligned against, to what tolerance, on which test,
and how closely it matched. Each row traces to a committed test artifact (the
pinned StatsPAI ↔ R ↔ Stata harness, version-locked via renv.lock + per-run
provenance) — nothing is asserted from memory.
import statspai as sp

s = sp.parity_status("feols")
print(s)
# feols: bit-exact vs fixest::feols [py/R/Stata] (headline rel_est 5.2e-15 within rel_est<=1e-06, rel_se<=1e-06)
s["reference_versions"]          # {'R': 'R version 4.5.2 (2025-10-31)', 'fixest': '0.14.0'}

sp.parity_summary()              # coverage counts, including the unverified gap
sp.parity_matrix(status="bit-exact")
Grades: bit-exact (headline relative error ≤ 1e-6 against a named R/Stata
reference), aligned (a documented, pre-registered looser tolerance),
analytical-only (recovers a known DGP truth or closed-form identity),
external-replication (reproduces published-paper numbers), and unverified
(registered but no parity evidence attached yet — the honest gap). The full,
auto-generated matrix is published at
docs/parity.md.
For your own data, sp.cross_validate re-runs one estimand through every
independent engine installed locally and reports whether they agree:
card = sp.datasets.card_1995()
cv = sp.cross_validate(card, "iv", y="lwage", endog=["educ"], instruments=["nearc4"],
                       covariates=["exper", "expersq", "black", "south", "smsa"])
print(cv.summary())
Engine Estimate Std.Err 95% CI status
------------------------------------------------------------------------
statspai 0.13229 0.04923 [0.0358, 0.2288] ok
pyfixest 0.13229 0.04923 [0.0358, 0.2288] ok
linearmodels 0.13229 0.04918 [0.0359, 0.2287] ok
R::fixest 0.13229 0.04923 [0.0358, 0.2288] ok
------------------------------------------------------------------------
VERDICT: ✓ AGREE (4/4 engines ran)
Engines that are not installed (pyfixest, or R with fixest) are skipped. The
linearmodels standard error differs in the fourth digit because it omits the
small-sample correction — a documented convention difference, not a
disagreement about the estimate.
Beyond point-parity, a Track-B coverage study runs B=1000 Monte Carlo
replications per estimator and checks that 95% confidence intervals hit their
nominal rate on known-truth DGPs, against a 99% Wilson acceptance band of
[0.935, 0.967]. The eleven materialized nominal rows — OLS on an RCT (0.952),
a 2×2 DiD (0.955), strong-instrument IV (0.962), Callaway–Sant'Anna staggered
ATT (0.947), Sun–Abraham overall ATT (0.950), a two-way FE panel (0.948), SDID
with placebo SEs (0.939), sharp RD with the robust CI (0.934), entropy
balancing (1.000), DML IRM ATE (0.968), and a causal-forest AIPW ATE (0.977) —
fall inside the band for the first seven; the RD row sits just below it (mild
finite-sample under-coverage on a curved DGP), and the last three are above it
(conservative). The committed artifacts live under
tests/coverage_monte_carlo/results_b1000/.
Release notes live outside the README:
- CHANGELOG.md for the full version history.
- MIGRATION.md for deprecations and correctness fixes that change numbers.
- Docs changelog page for the rendered documentation site.
The README is intentionally focused on first-time users.
StatsPAI is described in a peer-reviewed paper in the Journal of Open Source Software (2026, 11(125), 10604): https://doi.org/10.21105/joss.10604. The reviewer-facing material prepared for that review remains the quickest way to audit the package:
If you use StatsPAI in research, cite the JOSS paper (preferred) and the
underlying method papers for each estimator. sp.citation() returns the paper
citation, sp.citation(which="software") the versioned software entry, and
many result objects expose estimator-level citation helpers.
@article{wang2026statspaijoss,
  author  = {Wang, Biaoyue and Rozelle, Scott},
  title   = {StatsPAI: A Unified, Agent-Native Python Toolkit for
             Causal Inference and Applied Econometrics},
  journal = {Journal of Open Source Software},
  year    = {2026},
  volume  = {11},
  number  = {125},
  pages   = {10604},
  doi     = {10.21105/joss.10604},
  url     = {https://doi.org/10.21105/joss.10604}
}

@software{wang2026statspai,
  author  = {Wang, Biaoyue and Rozelle, Scott},
  title   = {StatsPAI: A Unified, Agent-Native Python Toolkit for
             Causal Inference and Applied Econometrics},
  year    = {2026},
  version = {1.28.0},
  doi     = {10.5281/zenodo.19933900},
  url     = {https://doi.org/10.5281/zenodo.19933900},
  license = {MIT}
}MIT. See LICENSE.